
GUIDES
Big data in retail: what it actually means ow
Big data in retail refers to the volume, variety and velocity of data a retailer generates: line item transactions, browsing behaviour, inventory movement, loyalty activity, service contacts, reviews and third-party signals. The term comes from an era when simply storing and processing all of that was the difficult part, which for most retailers it hasn't been for years.
Storage is cheap now and processing is largely solved, so whatever separates the retailers getting value out of their data from the ones who aren't, it has very little to do with how much of it they hold.
What counts as big data in a retail business
Put real numbers against it and the picture changes fairly quickly. A mid-market omnichannel retailer is usually working with a few million line item transactions a year, tens of millions of web events, a product catalogue somewhere in the thousands, and loyalty and service records in the hundreds of thousands.
By the standards the term was coined for, none of that is big. It sits comfortably inside what an ordinary database has handled for a decade, which is rather the point. Most retailers never had a volume problem, and the ones who thought they did were usually describing something else in the only vocabulary available at the time.
Why volume was never the constraint
Three things genuinely limit what a retailer gets out of its data, and size isn't among them.
The first is resolution. The same customer turns up in the ecommerce platform, the point of sale (POS) system and the loyalty programme as three separate people, and no quantity of additional data corrects that. More data tends to make it worse, since every new source contributes another version of the same person.
The second is completeness in the fields that matter, which is almost always a polite way of saying product cost. A retailer can hold ten years of clean transaction history and still have no way to calculate gross margin per customer, because cost lives in the merchandising system and nobody ever joined the two together.
The third is whether anyone outside a small technical group can actually use the thing. Data that needs a specialist to query is data most of the business can't touch, so the bottleneck simply relocates from the database to the analyst's queue, where it becomes considerably harder to expand.
A retailer with two years of well-resolved, cost-attached customer data will outperform one sitting on ten years of fragmented history, every time.
The five uses that pay for themselves
Five applications account for most of the value retailers realise in practice, and they're less exotic than the category's marketing suggests.
Ranking the customer base by gross margin rather than revenue tends to reorder the top decile substantially, and it changes who gets VIP treatment more or less immediately. Churn prediction, by which most retailers mean spotting a lengthening purchase gap before the customer has actually gone, is well understood but depends on complete cross-channel history, which is where it usually comes unstuck. Using sell-through velocity by store and by segment to decide where stock goes is one of the few applications where the operational payback shows up inside the same quarter.
The two that consistently surprise people are discount discipline and acquisition targeting. Finding the customers who buy at full price regardless and leaving them out of promotions is often the fastest margin improvement available to a retailer, and it costs nothing to implement. Building lookalike audiences from your highest-margin customers rather than your highest-spending ones changes acquisition performance more than most media teams expect, because the two lists overlap far less than anyone assumes.
Four of those five need product cost. That single field is the difference between analytics that describes the business and analytics that pays for itself.
Why projects stall
The failures look remarkably similar from the outside.
Projects that begin with a platform decision tend to discover several months in that the data was never ready and the technology was never the constraint. Projects that begin by building a warehouse frequently deliver excellent reporting and no marketing capability whatsoever, because warehouses store beautifully and resolve nothing, and identity has to be solved somewhere. Projects without a clear owner move slowly for reasons anyone could predict: marketing wants the segments, IT owns the pipes, finance owns cost and retail operations owns the POS, so anything requiring all four and reporting to none of them tends to stall at the first real disagreement.
The last one is subtler and more common than it should be. Dashboards get built, reports get shipped, and nobody ever asks whether a decision changed as a result. A data programme that hasn't altered a buy, a send or a budget hasn't worked, however much data sits behind it.
What has to be true first
Three conditions, none of them negotiable: one customer is one record, product cost is attached to the line item, and someone who isn't a specialist can get an answer without lodging a request.
Meet all three with two years of history and the value turns up. Miss any one of them and ten years won't help.
Where Lexi fits
Lexi is built around those three conditions rather than around volume.
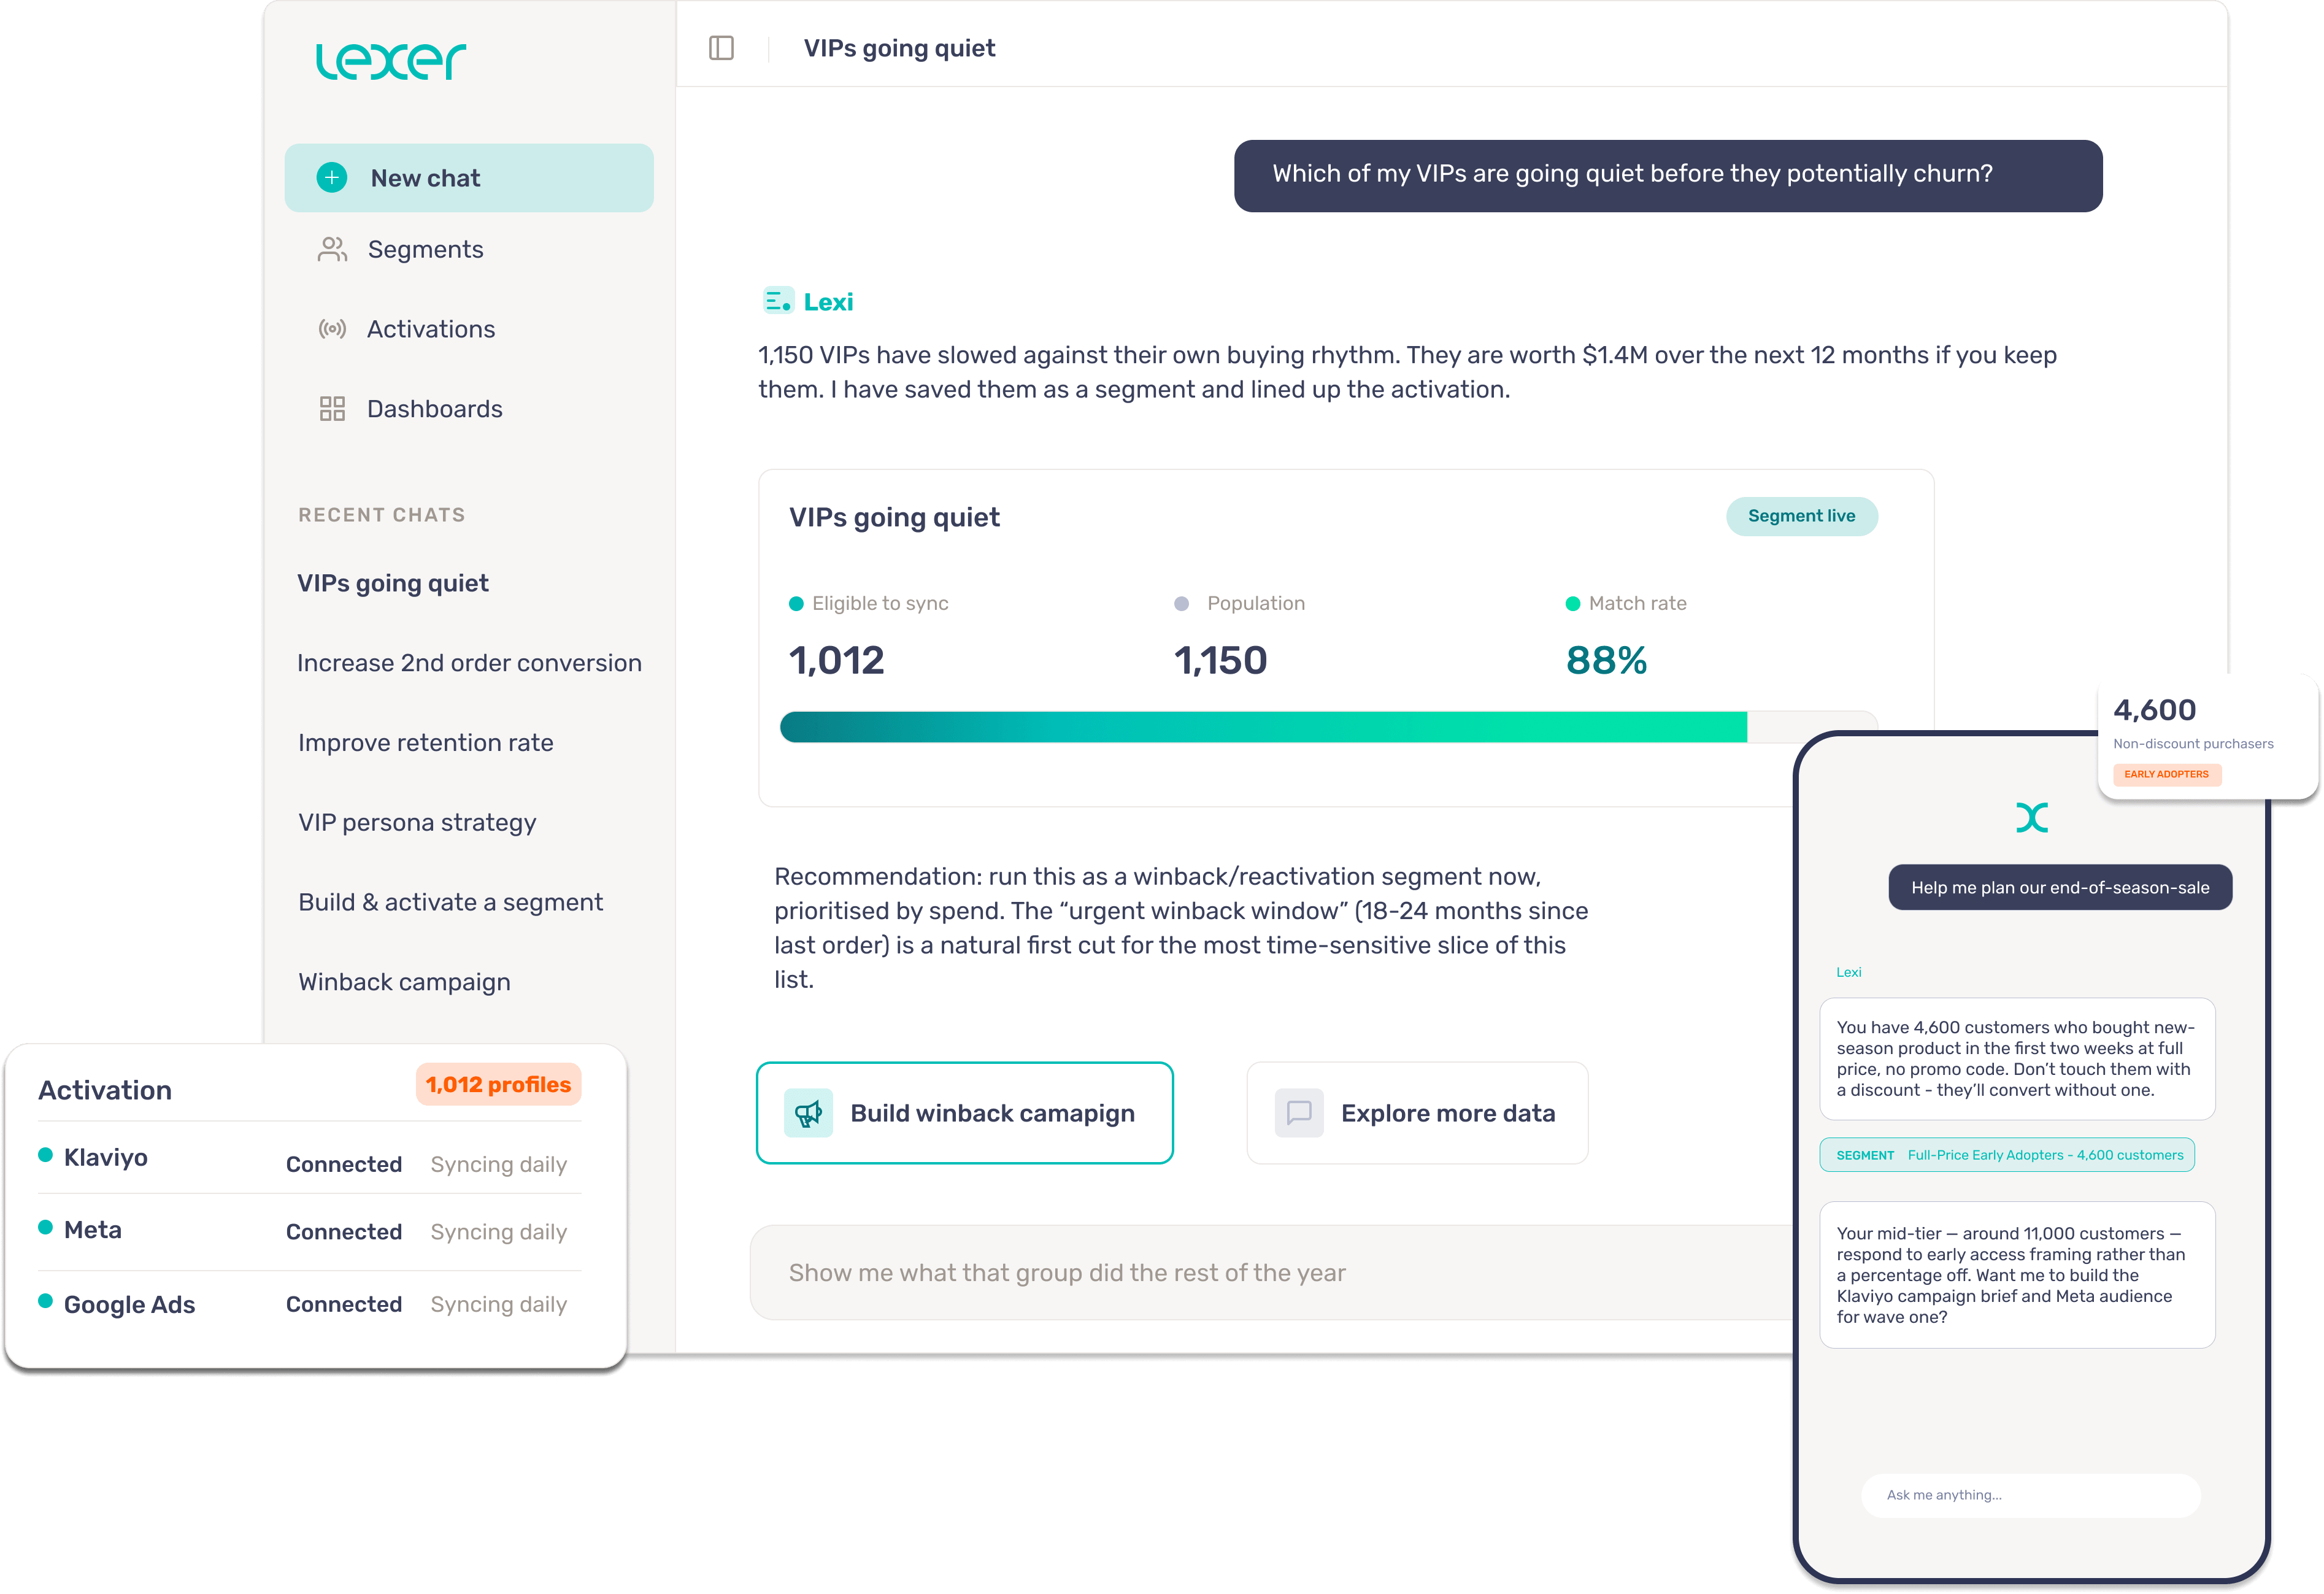
It ingests transactions, inventory, POS, loyalty, reviews and signals, resolves identity across every touchpoint, and holds product cost alongside the order, which between them cover the first two conditions. The third is the one that changes how a team spends its week. You ask a question in plain language, Lexi builds the answer from your data and shows the calculation behind it, then builds the segment and pushes it out to the tools your team already runs.
Lexi runs inside AWS Bedrock, data never leaves the platform, no personally identifiable information enters AI processing, and Lexer is SOC 2 certified.
A realistic starting point
Don't start with a data strategy. Start with one question the business genuinely can't answer today and would act on if it could.
The good candidates tend to be specific rather than sweeping: which customers are most likely to lapse in the next sixty days, which first purchase leads to the highest lifetime margin, which stores recruit customers who then go on to buy online. All three are answerable with data most retailers already hold, once it's been resolved. Answer one of them properly, act on what it tells you, then measure what happened. That will shape the next investment better than any strategy document.
Related Articles
📄 Customer Data Platform (CDP)
📄 Customer Intelligence Platform
📄 Retail Data Analytics Solutions
📄 Customer Experience in Retail
Common questions
What is big data in retail?
Big data in retail refers to the volume, variety and speed of data a retailer generates: line item transactions, web behaviour, inventory movement, loyalty activity, service contacts and reviews. The term comes from a period when storing and processing that volume was difficult. For most retailers today the constraint is resolution and completeness rather than size.
What are examples of big data in retail?
Line item transaction data from point of sale and ecommerce, web and app behaviour, inventory and sell-through movement, loyalty membership and points activity, service tickets and returns, product reviews, and third-party demographic enrichment. The most valuable and most often missing field is product cost, which is what makes margin analysis possible.
Do small retailers need big data?
Small and mid-market retailers rarely have a volume problem. What they usually need is resolved customer identity, product cost attached to transactions, and a way for non-specialists to ask questions. Two years of well-organised data outperforms ten years of fragmented data, so scale is seldom the limiting factor.
See how Lexi helps retailers drive more sales.
Leading retailers unify their customer data, build high-value audience segments, and grow lifetime value with Lexi.
Book a demo